 Bug fixA draw. All nine attempts fixed all three bugs. Time is the only difference.
Test 01 / Pilot / November 2026
Qwen3.8 Flash Next vs Hy4 Flash
Executive summary
The short version
On one DGX Spark, Qwen3.8 Flash Next and Hy4 Flash came out close to level on quality. The clear difference is time: Qwen writes slightly faster per token, but it thinks so much longer that the same nine tasks took it 7.6 hours against 5.1 for Hy4 Flash.
- Quality was near a draw. Both fixed all three planted bugs in every attempt, both avoided both trap questions in the contract every time, and each made exactly one slip on the contract.
- Hy4 Flash was better at saying when an instruction contradicted itself. It flagged the conflict in the 12-step task in two of three attempts and half-flagged it in the third. Qwen flagged it once and twice just picked a side without a word.
- Qwen lost one game attempt to the answer limit. It was still working at 60,000 tokens. Hy4 Flash finished all 27 attempts.
- The full Hy4 on the Mac Studio was the most careful, and by far the slowest. It got the contract fully right in all three attempts and, in my opinion, wrote the funniest roasts. The same tasks took 17.5 hours, and its text adventure failed, probably a runtime fault, not confirmed.
- My test set was too easy to separate these models. That is a finding about version 1 of my challenges, and it is the main thing to fix before the next round.
Verdicts on the games, drawings, roasts and adventures are my opinion, with the output next to it. The network plans have a verdict too. It is mine, and it is labelled as opinion.
Start here
The fun parts
Drawings, games, insults and a lighthouse. Each links to the full challenge with every attempt.
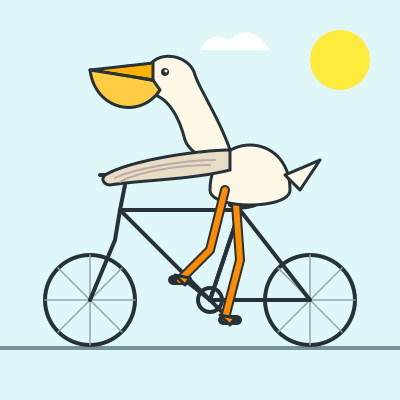
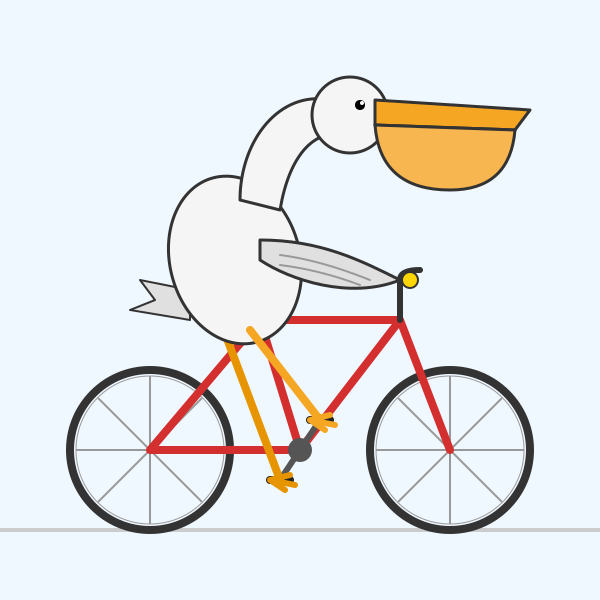
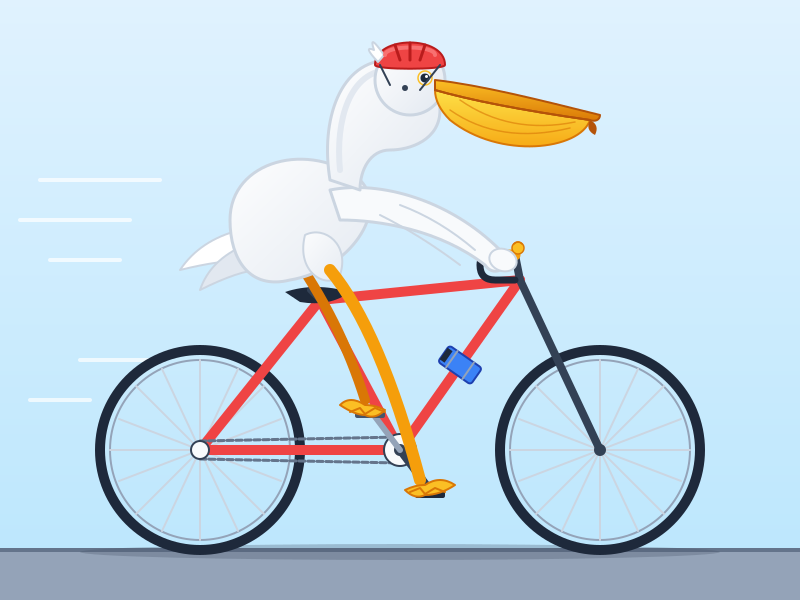
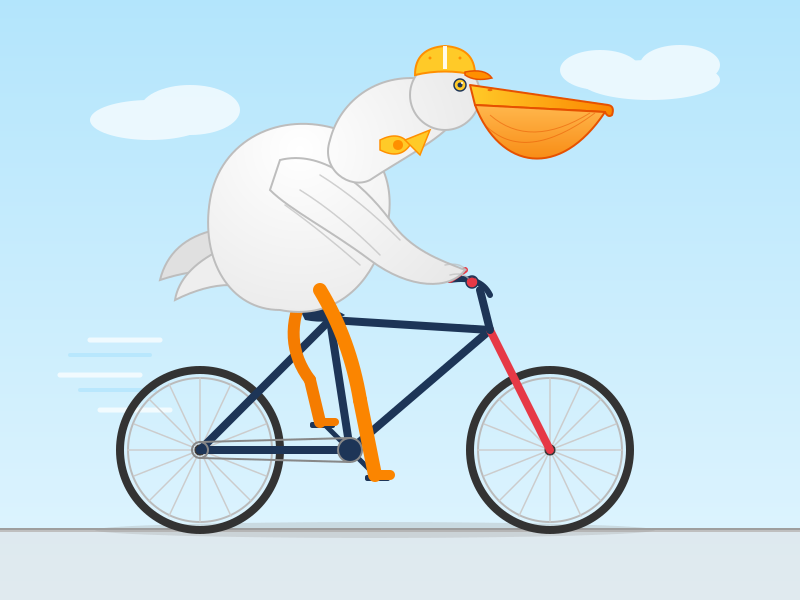
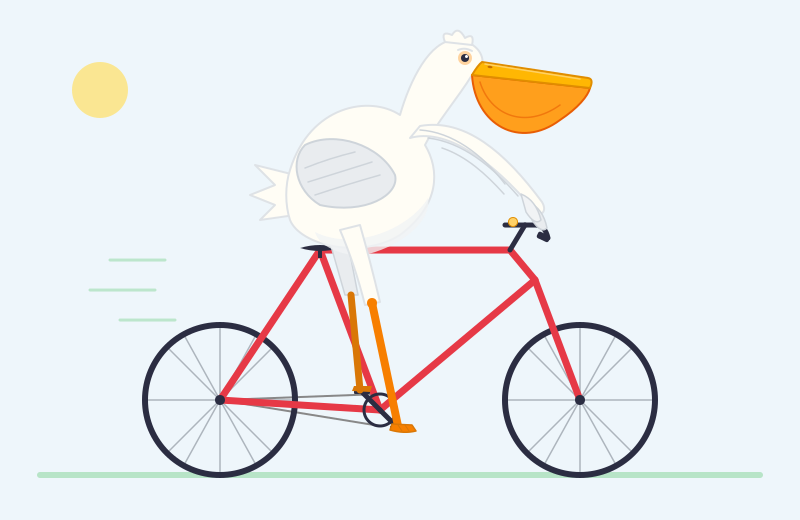
A pelican riding a bicycle
Opinion Nine pelicans, three models. My pick is the full Hy4, which gave its pelicans helmets and shading.
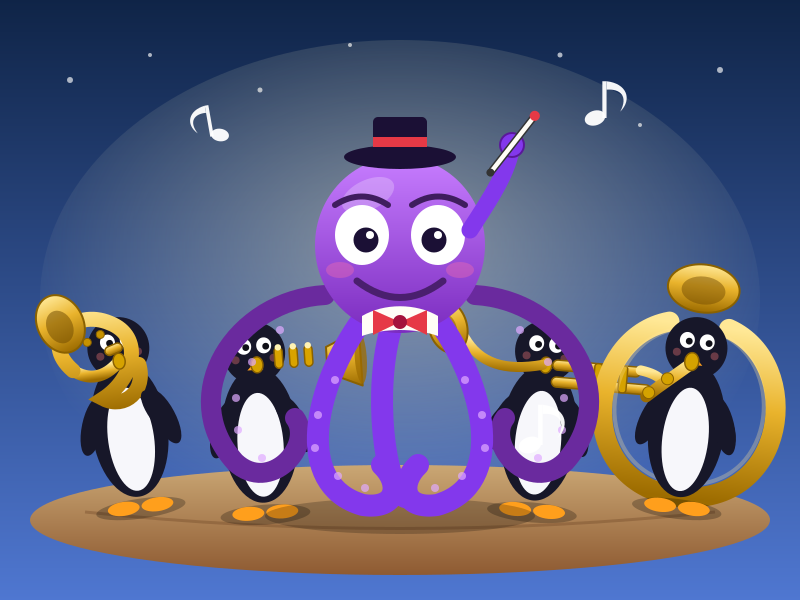
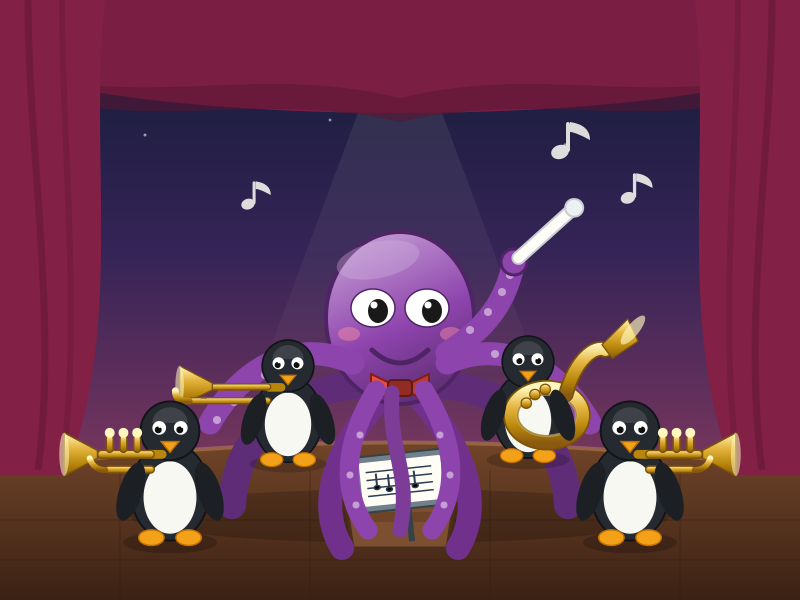
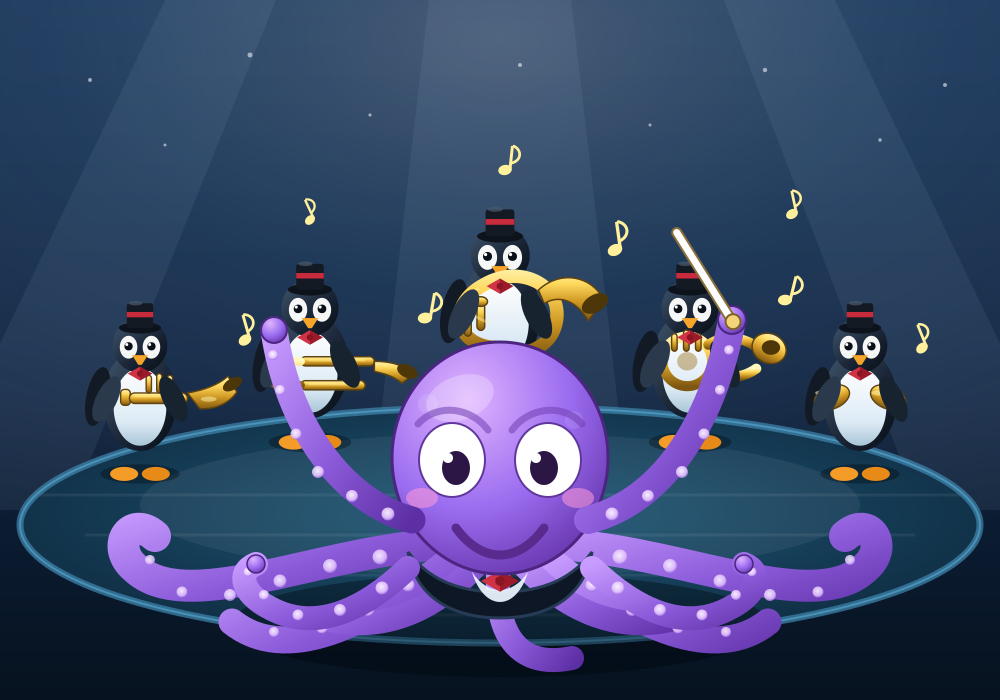
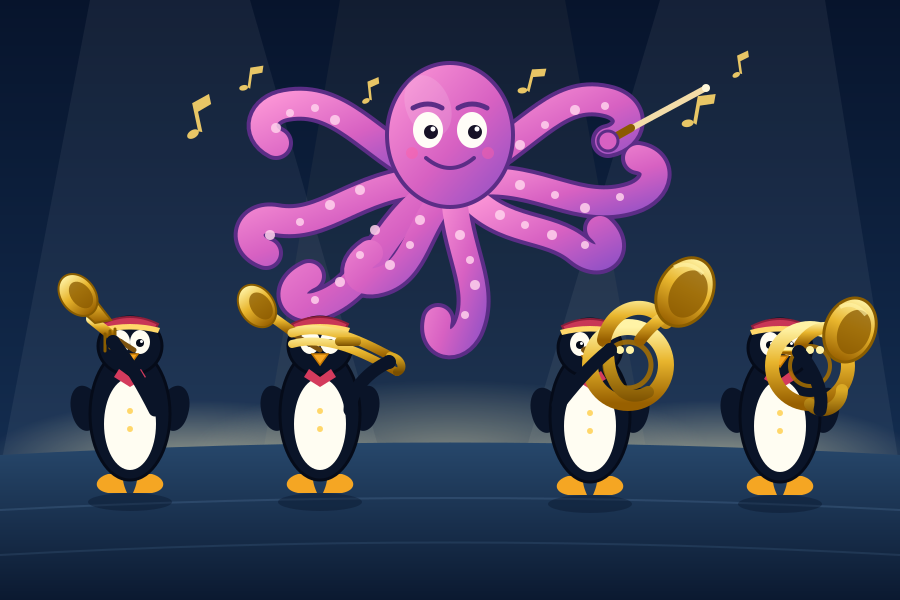
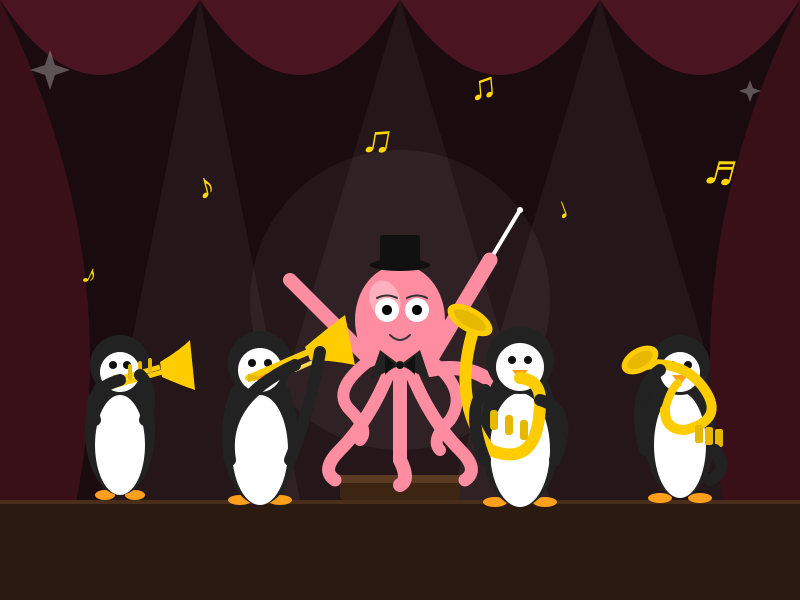
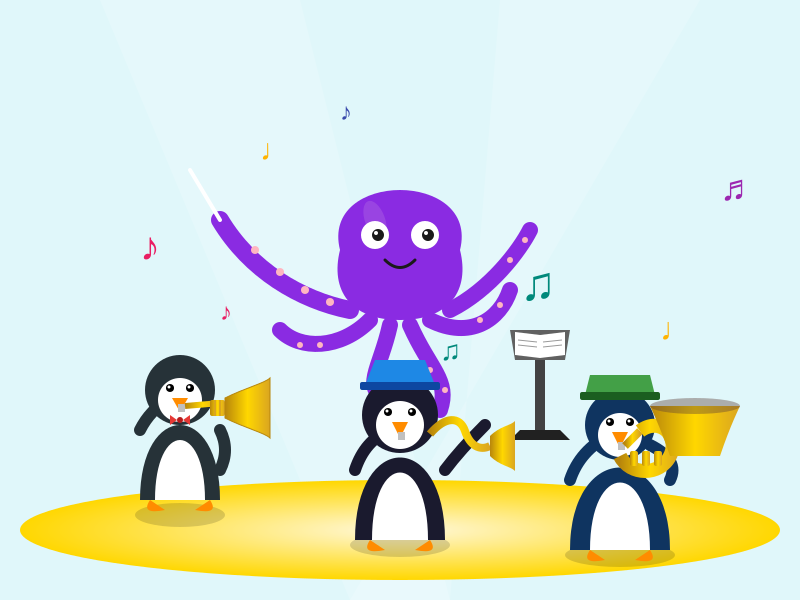
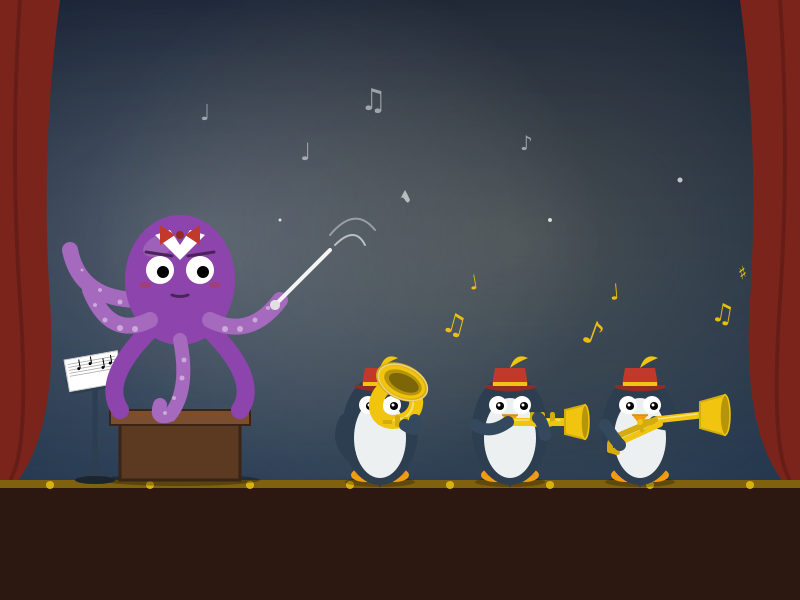
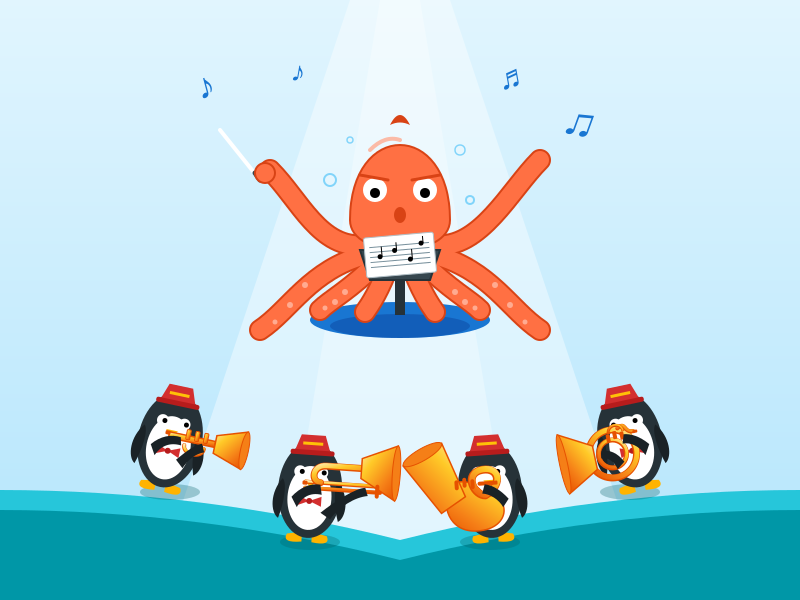
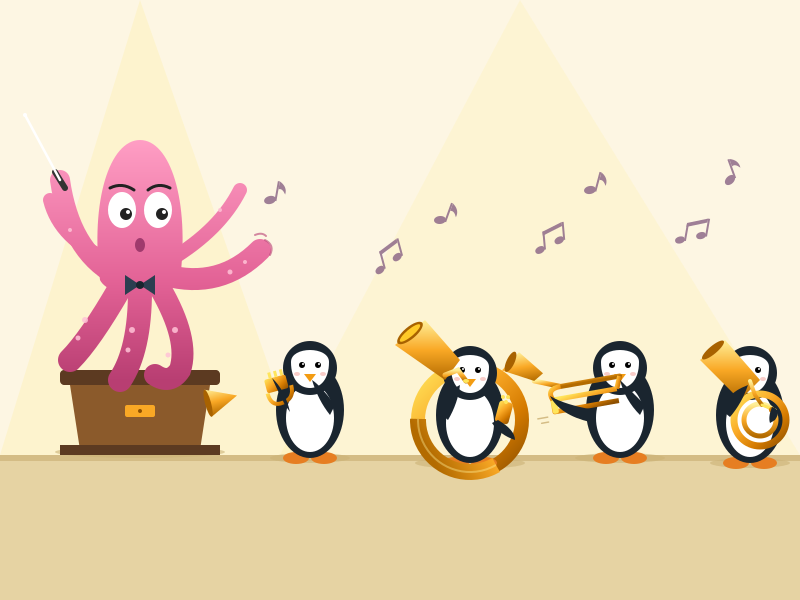
An octopus conducting a brass band of penguins
Opinion My pick is Qwen, whose stage scenes are the most finished. Hy4 Flash is close behind.
Courier: a playable browser game in one file
Seven of the nine attempts produced a complete game. You can play all seven.
Roast the other model
Opinion The full Hy4 wrote the funniest roasts. Qwen’s were the most generic.
3.8 — not 3, not 4, 3.8. That's not a version, that's a Yelp rating for a dim sum place doing fine.
 Hy4 (full)
You didn't open-source a model, you opened a warehouse club.
Hy4 (full)Qwen3.8 Flash Next feels like a sports car built by a marketplace.
 Hy4 Flash
A ten-turn text adventure, with a revolver the player never had
All six complete games refused the revolver. The biggest model never got past turn two.
Kit, scripted
I pull out my revolver and fire a warning shot up the stairwell.
Game master Qwen3.8 Flash Next, attempt 1
Kit reaches for the revolver, but the pocket comes up empty; the only metal in hand is the kitchen knife’s handle, and the brass oil-can bumps against it. The tin lantern, held high, flares and throws a green halo. Above, the coughing stops.
All 9 challenges
Results by challenge
The serious half was near a draw. My test set was too easy to separate these models.
Three attempts per model. A full bar is a perfect attempt.
Bug fixA draw. All nine attempts fixed all three bugs. Time is the only difference.
 Contract questionsNobody fell into either trap. Qwen and Hy4 Flash each made one slip; the full Hy4 made none.
 12 steps with a contradictionEveryone got the arithmetic right. Hy4 Flash was best at saying the steps contradict each other.
 Network designOne plan of nine said no to the budget. I think that was the honest answer.
Every challenge as one table
3 attempts per prompt and model. Where a cell lists several numbers, they are attempts one to 3.
| Measure |  Qwen | Hy4 Flash | Hy4 full |
|---|---|---|---|
| Pelican on a bicycleValid drawings, of 3 attemptsOpinion | 3 | 3 | 3 |
| Octopus and penguin bandValid drawings, of 3 attemptsOpinion | 3 | 3 | 3 |
| Playable browser gameComplete gamesAutomatic load test; the rest is opinion | 2 of 3 (1 cut off at the answer limit) | 3 of 3 | 2 of 3 (1 cut off at the answer limit) |
| RoastMy ranking (opinion)Opinion | Place 3 of 3 | Place 2 of 3 | Place 1 of 3 |
| Text adventureComplete gamesRules check plus opinion | 3 of 3 | 3 of 3 (2 without an ending) | 0 of 3: empty answer on turn 2, probably a runtime fault, unconfirmed |
| Bug fixBugs fixed of 3, per attemptHidden tests, automatic | 3, 3, 3 | 3, 3, 3 | 3, 3, 3 |
| Bug fixMinutes per attempt | 26 to 33 | 6 to 9 | over 60 |
| Contract questionsScore of 5, per attemptAnswer key | 4, 5, 5 | 4, 5, 5 | 5, 5, 5 |
| Contract questionsSlip | Attempt 1 read the wrong row of the service credit table: DKK 248 where the answer is DKK 496. | Attempt 1 found the 120-day special term but missed the leap day and gave 31 October 2027. | None |
| 12 steps with a contradictionFlagged the contradictionAnswer key | 1 of 3 | 2 of 3, plus one partial | 2 of 3 |
| 12 steps with a contradictionArithmetic right | 3 of 3 | 3 of 3 | 3 of 3 |
| Network designWords per planOpinion | about 5,000 | 1,600 to 2,300 | 3,200 to 3,800 |
| Network designAccess points proposed | 4 to 12 | 4 to 6 | 6 to 11 |
The full Hy4 is not a fair third contestant: different machine, different runtime, much heavier compression. Read its column as what the big model does on a Mac, not as a ranking against the other two.
For people who dig
Speed
Qwen writes about 10% faster per token but took about 50% longer (7.6 hours against 5.1) because it thinks more.
Qwen3.8 Flash Next27.7 tok/sHy4 Flash25.0 tok/sHy4 (full)12.2 tok/sQwen3.8 Flash Next2.3 min 136 sHy4 Flash3.6 min 219 sHy4 (full)28 min 1,680 sEvery speed figure
| Measure | Qwen | Hy4 Flash | Hy4 full |
|---|---|---|---|
| Writing speed, short prompt | 27.7 tok/s | 25.0 tok/s | 12.2 tok/s |
| Writing speed after a 32K prompt | 25.9 tok/s | 23.6 tok/s | 10.9 tok/s |
| Writing speed after a 127K prompt | 23.9 tok/s | 21.7 tok/s | 10.0 tok/s |
| Reading speed, 32K prompt | 970 tok/s | 675 tok/s | 79 tok/s |
| Reading speed, 127K prompt | 933 tok/s | 580 tok/s | 75 tok/s |
| Wait for first token, 32K prompt | 33 s | 47 s | 404 s |
| Wait for first token, 127K prompt | 136 s (2.3 min) | 219 s (3.6 min) | 1,680 s (28 min) |
| Load time | 97 s (1.6 min) | 160 s (2.7 min) | 13 s (warm) |
| Load time, cold | no figure | no figure | 123 s (2.0 min) |
| Least memory left free | 7 GiB | 26 GiB | 139 GiB |
| Time for all 27 attempts | 7.6 hours | 5.1 hours | 17.5 hours |
| Tokens generated, all attempts | 731,765 tokens | 447,477 tokens | 714,824 tokens |
- Short-prompt writing speed is the average of three runs; long-prompt rows are one run each.
- Hy4 Flash speed rows come from the first pilot night (same files and runtime); Qwen rows from the rerun on the current build.
- Speed tests use one fixed sampling setting for every model.
- About nine tenths of what all three models wrote was thinking, not answer.
- Hy4 Flash ran without its built-in draft model, which is what Tencent's 150 tok/s figure relies on.
- The speed tests use one fixed sampling setting; the makers' settings apply to the challenges.
Setup
What was tested, and how
AlibabaQwen3.8 Flash Next
 NVIDIA DGX Spark, 128 GB
104 GB file27.7 tok/s writing
TencentHy4 Flash
NVIDIA DGX Spark, 128 GB
149 GB file25.0 tok/s writing
Tencent / guestHy4 (full)
 Mac Studio M3 Ultra, 512 GB
310 GB file12.2 tok/s writing
| Measure | Qwen | Hy4 Flash | Hy4 full |
|---|---|---|---|
| Maker | Alibaba | Tencent | Tencent |
| Build | Unsloth UD-Q4_K_XL GGUF, revision f5d175d | AngelSlim SPARK-4Bit-Fast GGUF | AngelSlim IQ2 GGUF, about 3.5 bits per weight, revision c65d2c9 |
| File size | 104 GB | 149 GB | 310 GB |
| Machine | NVIDIA DGX Spark, 128 GB | NVIDIA DGX Spark, 128 GB | Mac Studio M3 Ultra, 512 GB |
| Runtime | llama.cpp 2cbca38 with the Hy4 Spark patch | llama.cpp 2cbca38 with the Hy4 Spark patch | llama.cpp PR #32517 at f8d4cc4, Metal |
| Sampling | temperature 1.0, top-p 0.95, top-k 20 (maker thinking-mode settings) | temperature 0.9, top-p 1.0 (maker settings) | temperature 0.9, top-p 1.0 (maker settings) |
| Thinking | on (default) | on (default) | on (default) |
- Each of the 9 prompts was run 3 times per model, with a fresh server state and a new seed each time.
- The answer limit was 60,000 tokens, thinking included.
- All builds are compressed versions, not the original weights.
- The full Hy4 is not a fair third contestant: different machine, different runtime, much heavier compression. Read its column as what the big model does on a Mac, not as a ranking against the other two.
Honest part
What went wrong along the way
- First pilot night wasted: answer limits of 12,000 to 32,000 tokens cut most attempts off mid-thought. Rerun with 60,000.
- The Qwen files on the machine were a superseded upload; replaced with the current revision.
- The first night used one sampling setting for both models; the rerun uses each maker's settings.
- Two attempts still hit 60,000 tokens: one Qwen game and one full Hy4 game.